AI Talking Avatar
A presenter generated from a single photo, reading your script to camera — the format behind most explainer, onboarding and UGC-ad content.
SnapVivid cannot do this today. A talking avatar needs two things: speech synthesis, which does ship — the AI Voiceover tool reads a script aloud — and lip-sync, which does not. Nothing on SnapVivid makes a face form words, on any plan. What ships is image generation, image-to-video, and audio as separate files you mix yourself.
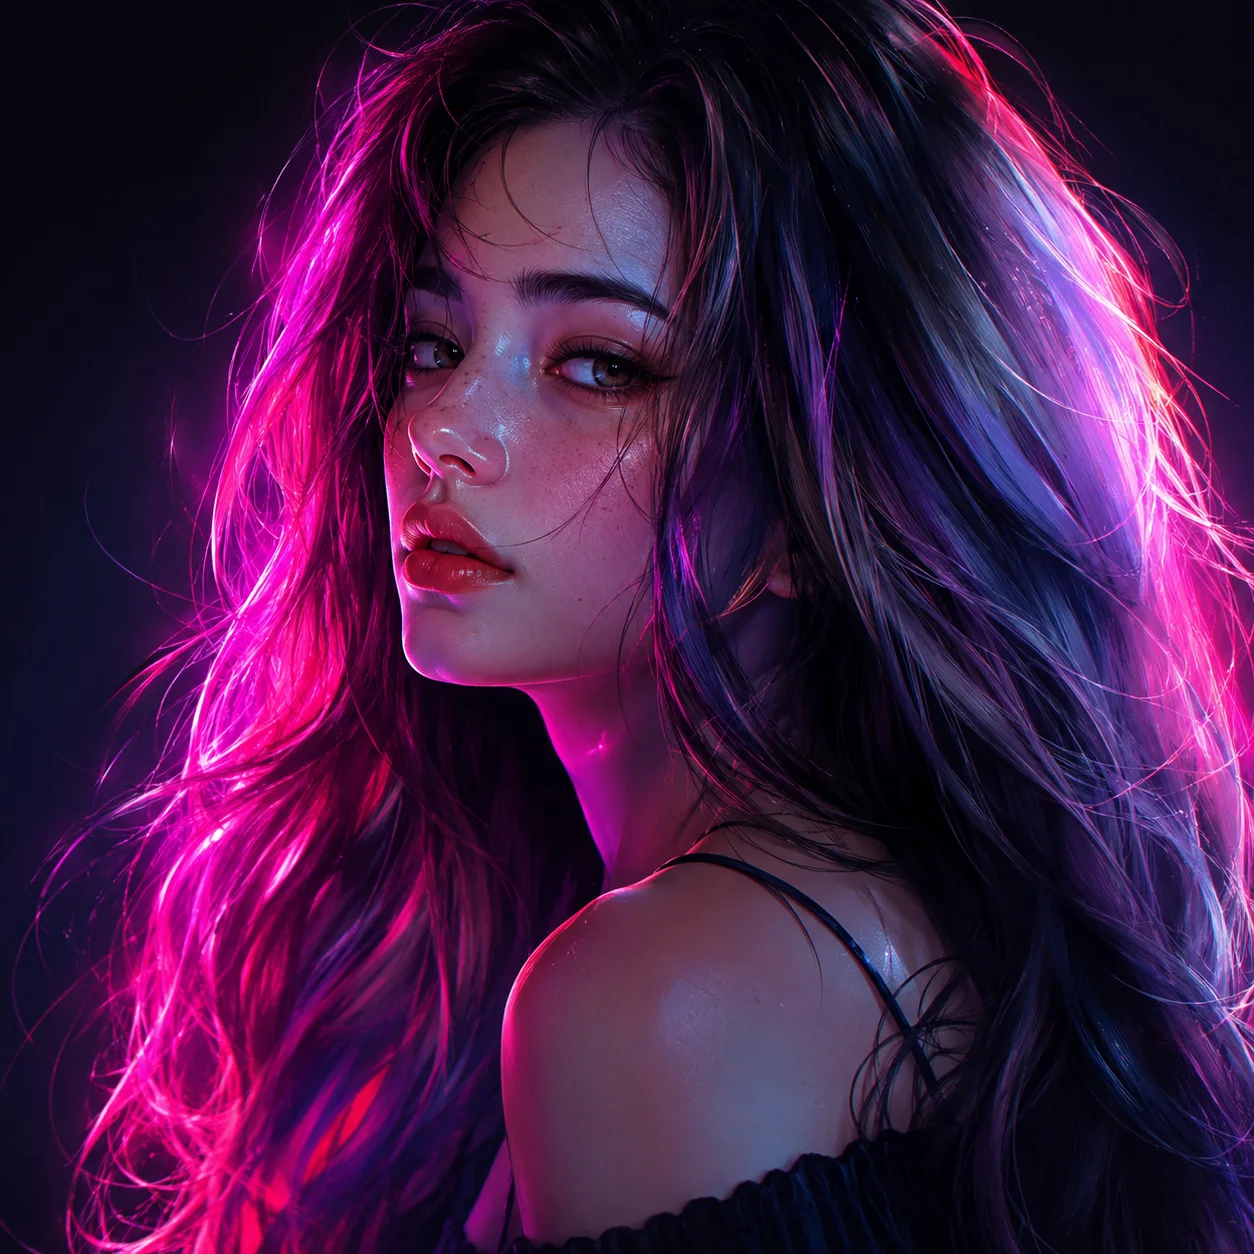
A real SnapVivid render. The face moves naturally, but it is not speaking and no words are being synced — that is the unbuilt part.
What a talking avatar would add
The scoped shape of the feature. None of it is available today.
Script to spoken delivery
Paste a script and have a generated presenter read it, instead of booking a person and a camera for every update.
Lip movement that matches
Mouth shapes driven by the audio rather than looped generic motion — the difference between a presenter and an uncanny loop.
Consent-gated likeness
A presenter built only from a photo you have the right to use, with the same consent discipline planned for voice cloning.
What SnapVivid does generate today
Portraits with real, natural motion — the face just never speaks. Generate or upload a face, then let the portrait video generator add a head turn, a blink, a shift of light. It is genuinely good for hooks, intros and b-roll; it will not deliver a line of dialogue, and we are not going to imply that it will.
Good to know
Straight answers about the most over-promised feature in this category.
Can any SnapVivid tool make a photo speak?
No. Not the portrait video generator, not the video studio, not any effect. Faces can move; they cannot form words to an audio track, because there is no lip-sync model — and video renders carry no audio track of their own. You can generate the voice separately and lay it under the clip, but the mouth will not match it. If a page anywhere suggests otherwise, it is wrong.
What about UGC ads with a spokesperson?
The talking half is not available. The footage half is — the UGC video generator produces creator-style product cutaways from stills, which you can cut around a real person’s piece to camera. That is an honest split of the work rather than a promise to replace the presenter.
When will it ship?
No announced date. Speech synthesis has landed; a lip-sync model has not, and that is the whole remaining build — so treat this as unavailable rather than imminent when you plan.
Want to know when talking avatars land?
Send one email and we will let you know when it is genuinely available.
Email us to be notifiedOpens an email to support@snapvivid.com — no account or payment needed.
What works today
Shipped SnapVivid surfaces you can use right now.
The audio half, which does ship
Speech and sound are live — it is the lip-sync that is missing.